Loading...
Searching...
No Matches
Public Types |
Public Member Functions |
Protected Member Functions |
Protected Attributes |
Friends |
List of all members
FST::Model_Multinomial< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR > Class Template Reference
Multinomial ("bag of words") model: per-class term-count sums and the Laplace-smoothed term probabilities P(term|class) derived from them. More...
#include <model_multinom.hpp>
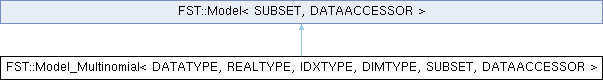
Inheritance diagram for FST::Model_Multinomial< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >:
Public Types | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying train blocks | |
| typedef std::shared_ptr< SUBSET > | PSubset |
| shared pointer to a feature subset, as consumed by learn()/narrow_to() | |
| Public Types inherited from FST::Model< SUBSET, DATAACCESSOR > | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying training data | |
| typedef std::shared_ptr< SUBSET > | PSubset |
| shared pointer to a feature subset, as consumed by narrow_to() | |
Public Member Functions | |
| Model_Multinomial (const Model_Multinomial &mm) | |
| Deep-copies all learned buffers (sufficient statistics, theta/MI/IB caches, index maps). | |
| virtual void | learn (PDataAccessor da) override |
Fits the model's parameters from da's training data, over all its features. Concrete models may additionally offer a (da, subset) convenience overload to learn at a lower dimensionality directly - that is not part of this interface, so generic code must not assume it exists. narrow_to()/denarrow() do NOT relearn – they only change which features of an ALREADY-learned model are exposed to subsequent evaluation. | |
| virtual void | learn (PDataAccessor da, const PSubset sub) |
Learns the model restricted to sub's selected features. Computes only the sufficient statistics (_Nsuminclass, class priors _Pc, _Pc_d) via compute_Nsuminclass(); it does NOT fill _theta/_MI/_IB – call compute_theta() (and, for the full feature set, compute_MI()/compute_IB()) explicitly afterwards. Reallocates buffers when the class count or sub's raw dimensionality exceeds current capacity; otherwise reuses them. Leaves the model unnarrowed (_d=_n). | |
| void | narrow_to (const PSubset sub) override |
| void | denarrow () override |
| Undoes narrow_to(): model access reverts to the full dimensionality it was learned at. | |
| void | compute_theta () |
| Computes the Laplace-smoothed term-conditional probabilities _theta = P(feature|class) and _doc_avg_length, over the currently exposed dimensionality (_d, via narrow_to()/denarrow()). | |
| void | compute_MI () |
| Computes per-feature Mutual Information (fills _MI, full _n-length). | |
| void | compute_IB () |
| Computes per-feature "Individual Bhattacharyya" (fills _IB, full _n-length): the class-pair-averaged Bhattacharyya-like coefficient of each single feature's term distribution, weighted by _Pc_d and scaled by _doc_avg_length. | |
| DIMTYPE | get_n_max () const |
| allocated buffer capacity (dimensionality upper bound) | |
| DIMTYPE | get_n () const |
| "full feature set" dimensionality the model was learned at | |
| DIMTYPE | get_d () const |
| dimensionality currently exposed (post narrow_to()/denarrow()) | |
| DIMTYPE | get_classes () const |
| number of classes, as set by the last learn() call | |
| REALTYPE | get_doc_avg_length () const |
| average total term length per training pattern; valid after compute_theta() | |
| REALTYPE | get_Pc (const DIMTYPE c) const |
| class prior P(class=c), estimated in learn() from class sizes | |
Protected Member Functions | |
| const std::unique_ptr< REALTYPE[]> & | get_theta () const |
| raw P(term|class) buffer, class-major, valid at the dimensionality last passed to compute_theta() | |
| const std::unique_ptr< REALTYPE[]> & | get_IB () const |
| raw per-feature Individual Bhattacharyya buffer (full _n length), valid after compute_IB() | |
| const std::unique_ptr< REALTYPE[]> & | get_MI () const |
| raw per-feature Mutual Information buffer (full _n length), valid after compute_MI() | |
| void | compute_Nsuminclass (PDataAccessor da) |
| Sums raw per-class, per-(learn-subspace)-feature term counts into _Nsuminclass and sets _allpatterns. Called from learn(da,sub); the subspace is the one recorded in _learn_index. | |
Protected Attributes | |
| DIMTYPE | _classes |
| number of classes; initialized in learn(). NOTE: expressions like _classes*_n*_n are evaluated in std::size_t where they occur, so they do not overflow DIMTYPE | |
| DIMTYPE | _n_max |
| allocated buffer capacity (dimensionality upper bound); see the NOTE above | |
| DIMTYPE | _n |
| std::unique_ptr< DATATYPE[]> | _Nsuminclass |
| per-class, per-learn-subspace-feature raw term-count sums (class-major, stride _n); filled by compute_Nsuminclass() | |
| std::unique_ptr< REALTYPE[]> | _theta |
| P(term|class), Laplace-smoothed; class-major, stride = the _d in effect at the last compute_theta() call. | |
| std::unique_ptr< REALTYPE[]> | _Pc |
| per-class prior P(class), estimated in learn() from da->getClassSize()/getClassSizeSum() | |
| std::unique_ptr< REALTYPE[]> | _Pc_d |
| per-class share of total learn-subspace term length; computed in learn(), consumed by compute_MI()/compute_IB() | |
| std::unique_ptr< REALTYPE[]> | _Pv |
| per-feature marginal term probability scratch, used internally by compute_MI() | |
| std::unique_ptr< REALTYPE[]> | _MI |
| per-feature (full _n-length) Mutual Information scores, filled by compute_MI() | |
| std::unique_ptr< REALTYPE[]> | _IB |
| per-feature (full _n-length) Individual Bhattacharyya scores, filled by compute_IB() | |
| DIMTYPE | _d |
| "virtual subset" dimensionality currently exposed (<=_n), via narrow_to()/denarrow() | |
| std::unique_ptr< DIMTYPE[]> | _index |
| maps feature subset indexes to raw (full set) feature indexes, used for narrow()ing | |
| IDXTYPE | _allpatterns |
| total training pattern count summed over all classes; set by compute_Nsuminclass() (called from learn()) | |
| REALTYPE | _doc_avg_length |
| average total term length per training pattern; computed in compute_theta(), needed by compute_IB() | |
| std::unique_ptr< DIMTYPE[]> | _learn_index |
| maps the to-be-learned model's subspace positions to raw (full-set) feature indices; set by learn(da,sub) | |
Detailed Description
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
class FST::Model_Multinomial< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
class FST::Model_Multinomial< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
Multinomial ("bag of words") model: per-class term-count sums and the Laplace-smoothed term probabilities P(term|class) derived from them.
For every class the per-feature term counts of all training patterns are summed (compute_Nsuminclass()); compute_theta() turns those sums into the smoothed conditional probabilities
theta(f|c) = (1 + N(f,c)) / (d + sum over the exposed f' of N(f',c))
that is, add-one (Laplace) smoothing over the ACTIVE vocabulary: the d features currently exposed by narrow_to(), not the full feature set, so the probabilities of a feature subset are normalized within that subset. Class priors P(c) are estimated from the class sizes of the WHOLE data set the accessor holds (not the train part alone; identical under stratified splitting), while the term counts come from the TRAIN part. compute_MI() and compute_IB() add the per-feature Mutual Information and "Individual Bhattacharyya" rankings consumed by the multinomial criteria.
Unlike Model_Normal this model carries no mean/covariance and makes no continuity assumption – it is the discrete counterpart, intended for count data such as document term frequencies.
- Note
- The data values are assumed to be non-negative term counts. Nothing verifies it; negative or fractional values make the sums and the smoothed probabilities meaningless.
- Call order is learn() (or learn(da,sub)), then compute_theta(), then optionally compute_MI() / compute_IB() – and those two require compute_theta() to have been run at the FULL (denarrow()ed) feature set. The order is not enforced; calling out of order silently uses stale buffers.
Member Function Documentation
◆ compute_IB()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
| void FST::Model_Multinomial< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >::compute_IB | ( | ) |
Computes per-feature "Individual Bhattacharyya" (fills _IB, full _n-length): the class-pair-averaged Bhattacharyya-like coefficient of each single feature's term distribution, weighted by _Pc_d and scaled by _doc_avg_length.
- Note
- Same full-feature-set precondition on _theta as compute_MI().
◆ compute_MI()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
| void FST::Model_Multinomial< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >::compute_MI | ( | ) |
Computes per-feature Mutual Information (fills _MI, full _n-length).
- Note
- Requires compute_theta() to have been called at the FULL (denarrow()ed) feature set – this reads _theta densely over 0.._n per class, not through _index.
◆ compute_theta()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
| void FST::Model_Multinomial< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >::compute_theta | ( | ) |
Computes the Laplace-smoothed term-conditional probabilities _theta = P(feature|class) and _doc_avg_length, over the currently exposed dimensionality (_d, via narrow_to()/denarrow()).
- Note
- Requires learn()/learn(da,sub) to have populated _Nsuminclass/_allpatterns first. compute_MI()/compute_IB() additionally require this to have been called while denarrow()ed (_d==_n) – they index _theta over the full _n range directly.
◆ denarrow()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Undoes narrow_to(): model access reverts to the full dimensionality it was learned at.
Implements FST::Model< SUBSET, DATAACCESSOR >.
◆ learn()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Fits the model's parameters from da's training data, over all its features. Concrete models may additionally offer a (da, subset) convenience overload to learn at a lower dimensionality directly - that is not part of this interface, so generic code must not assume it exists. narrow_to()/denarrow() do NOT relearn – they only change which features of an ALREADY-learned model are exposed to subsequent evaluation.
Implements FST::Model< SUBSET, DATAACCESSOR >.
◆ narrow_to()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Restricts subsequent model access to sub's selected features, without relearning (analogous to Distance::narrow_to() – see there for the _index[] mechanism concrete models typically reuse).
Implements FST::Model< SUBSET, DATAACCESSOR >.
Member Data Documentation
◆ _n
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
protected |
"full feature set" dimensionality the model was learned at (<=_n_max); initialized in learn(). NOTE: expressions like _classes*_n*_n are evaluated in std::size_t where they occur, so they do not overflow DIMTYPE
The documentation for this class was generated from the following file:
- /Users/psms/dev/devtest1/_src_criteria/model_multinom.hpp
Generated by
 1.17.0