Loading...
Searching...
No Matches
Public Types |
Public Member Functions |
Protected Member Functions |
Protected Attributes |
Friends |
List of all members
FST::Model_Normal< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR > Class Template Reference
Implements normal (gaussian) model. More...
#include <model_normal.hpp>
Inheritance diagram for FST::Model_Normal< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >:
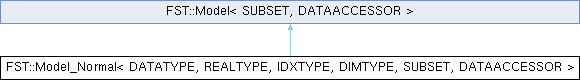
Public Types | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying training data | |
| typedef std::shared_ptr< SUBSET > | PSubset |
| shared pointer to a feature subset, as consumed by learn(da,sub)/narrow_to() | |
| Public Types inherited from FST::Model< SUBSET, DATAACCESSOR > | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying training data | |
| typedef std::shared_ptr< SUBSET > | PSubset |
| shared pointer to a feature subset, as consumed by narrow_to() | |
Public Member Functions | |
| Model_Normal (const Model_Normal &mn) | |
| copy-constructor (deep-copies the per-class mean/covariance arrays and the learn-time index map) | |
| virtual void | learn (PDataAccessor da) override |
Fits the model's parameters from da's training data, over all its features. Concrete models may additionally offer a (da, subset) convenience overload to learn at a lower dimensionality directly - that is not part of this interface, so generic code must not assume it exists. narrow_to()/denarrow() do NOT relearn – they only change which features of an ALREADY-learned model are exposed to subsequent evaluation. | |
| virtual void | learn (PDataAccessor da, const PSubset sub) |
Learns per-class mean vectors and covariance matrices restricted to sub's selected features. Sets get_n()==get_d()==sub->get_d_raw() and records the raw dataset feature id of each learned dimension in _learn_index; a subsequent narrow_to() must pass a subset with get_n_raw()==get_n() (i.e. a further restriction of THIS learned subspace, not of da's full feature space). | |
| void | narrow_to (const PSubset sub) override |
| void | denarrow () override |
| Undoes narrow_to(): model access reverts to the full dimensionality it was learned at. | |
| DIMTYPE | get_n_max () const |
| the allocated capacity (max n learn() can grow to without reallocating) | |
| DIMTYPE | get_n () const |
| the full ("raw") dimensionality the model is currently learned at, get_n()<=get_n_max() | |
| DIMTYPE | get_d () const |
| the current virtual (narrow_to()'d) dimensionality, get_d()<=get_n() | |
| DIMTYPE | get_classes () const |
| number of classes the model was learned over (learn()'s da->getNoOfClasses()) | |
| REALTYPE | get_Pc (const DIMTYPE c) const |
Protected Member Functions | |
| const std::unique_ptr< Indexed_Vector< REALTYPE, DIMTYPE, SUBSET >[]> & | get_mean () const |
| per-class learned mean vectors (array of get_classes() Indexed_Vector, each of dimensionality get_n()/get_d()); for the friend criteria/classifiers above | |
| const std::unique_ptr< Indexed_Matrix< REALTYPE, DIMTYPE, SUBSET >[]> & | get_cov () const |
| per-class learned covariance matrices (array of get_classes() Indexed_Matrix, each get_n()/get_d() sized); for the friend criteria/classifiers above | |
Protected Attributes | |
| DIMTYPE | _classes |
| number of classes the model is learned over; see get_classes() – NOTE: expressions like _classes*_n*_n are evaluated in std::size_t where they occur, so they do not overflow DIMTYPE | |
| DIMTYPE | _n_max |
| allocated capacity: the largest sub->get_n_raw() (the subset's full allocation size, at any learn(da,sub) call) _mean[]/_cov[] have been grown to hold | |
| DIMTYPE | _n |
| full ("raw") dimensionality the model is currently learned at, _n<=_n_max; see get_n() – NOTE: expressions like _classes*_n*_n are evaluated in std::size_t where they occur, so they do not overflow DIMTYPE | |
| std::unique_ptr< REALTYPE[]> | _Pc |
| per-class prior probabilities P(c), get_classes() entries; see get_Pc() | |
| std::unique_ptr< Indexed_Vector< REALTYPE, DIMTYPE, SUBSET >[]> | _mean |
| per-class learned mean vectors, get_classes() entries; see get_mean() | |
| std::unique_ptr< Indexed_Matrix< REALTYPE, DIMTYPE, SUBSET >[]> | _cov |
| per-class learned covariance matrices, get_classes() entries; see get_cov() | |
| DIMTYPE | _d |
| current virtual (narrow_to()'d) dimensionality, _d<=_n; see get_d() | |
| std::unique_ptr< DIMTYPE[]> | _learn_index |
Detailed Description
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
class FST::Model_Normal< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
class FST::Model_Normal< DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
Implements normal (gaussian) model.
Per class: the mean vector and the full covariance matrix, estimated from the accessor's currently designated TRAIN part, and the prior probability P(c), estimated from the class sizes of the WHOLE data set the accessor holds (getClassSizeSum(), see get_Pc()) - identical to the train-part frequency under stratified splitting. Each class keeps its OWN covariance (no pooling), which is what makes the components built on this model quadratic in the data: Classifier_Normal_Bayes is the QDA-style classifier, and the normal-model filter criteria (Bhattacharyya, generalized Mahalanobis, divergence) all read these per-class moments. Classifier_LDA is the pooled-covariance, linear counterpart and reuses the same moments.
Two independent notions of dimensionality live here. learn(da,sub) fixes what the model IS: it estimates the moments over sub's selected features only, and get_n() is that count. narrow_to() then selects a sub-subspace of the LEARNED one for reading, reported by get_d(); that is a cheap re-indexing, not a re-estimation. Feature indices passed to narrow_to() are therefore positions within the learned subspace, not raw dataset feature ids.
- Note
- Covariances are the unbiased estimates (divided by the class's training pattern count minus one). A class with fewer training patterns than features - or with exactly dependent features - yields a singular covariance, which the consumers cannot invert.
Member Function Documentation
◆ denarrow()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Undoes narrow_to(): model access reverts to the full dimensionality it was learned at.
Implements FST::Model< SUBSET, DATAACCESSOR >.
◆ get_Pc()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
inline |
Class prior probability P(c), estimated in learn() as class c's relative sample frequency over da.
- Note
- caller must ensure this is called only while the model's learned structures (_mean, _Pc, _cov) exist.
◆ learn()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Fits the model's parameters from da's training data, over all its features. Concrete models may additionally offer a (da, subset) convenience overload to learn at a lower dimensionality directly - that is not part of this interface, so generic code must not assume it exists. narrow_to()/denarrow() do NOT relearn – they only change which features of an ALREADY-learned model are exposed to subsequent evaluation.
Implements FST::Model< SUBSET, DATAACCESSOR >.
◆ narrow_to()
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Restricts subsequent model access to sub's selected features, without relearning (analogous to Distance::narrow_to() – see there for the _index[] mechanism concrete models typically reuse).
Implements FST::Model< SUBSET, DATAACCESSOR >.
Member Data Documentation
◆ _learn_index
template<typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
protected |
Maps each learned dimension (0.._n-1) back to the raw feature id it was learned from (the id supplied via learn(da,sub)'s sub->selected_features()); NOTE this is distinct from the narrow_to() mechanism inside _mean[]/_cov[] – it exists only to support learn(da,sub), not narrow()ing.
The documentation for this class was generated from the following file:
- /Users/psms/dev/devtest1/_src_criteria/model_normal.hpp
Generated by
 1.17.0