Loading...
Searching...
No Matches
Public Types |
Public Member Functions |
Protected Member Functions |
Protected Attributes |
Static Protected Attributes |
List of all members
FST::Classifier_RBF_SVM< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR > Class Template Reference
Dependency-free RBF kernel SVM trained by kernel dual coordinate descent (implemented from scratch, no LibSVM code; C-SVC with the RBF kernel only, deliberately NOT a LibSVM replacement: no nu-variants, no SVR, no one-class, no probability estimates, no shrinking). More...
#include <classifier_rbf_svm.hpp>
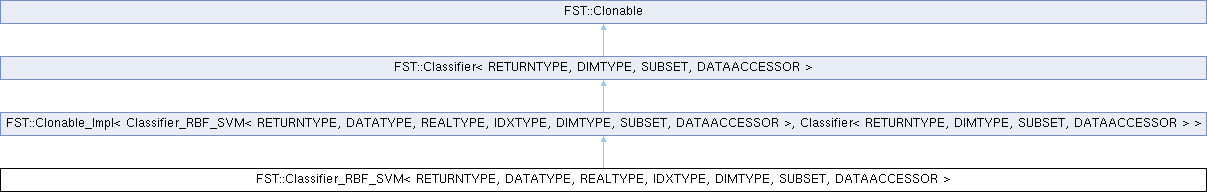
Inheritance diagram for FST::Classifier_RBF_SVM< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >:
Public Types | |
| typedef Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | parent |
| the immediate abstract base | |
| typedef Clonable_Impl< Classifier_RBF_SVM, parent > | parent_impl |
| implements clone() via the (implicit, member-wise) copy-constructor – all members are value-semantic | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying train/test blocks | |
| typedef std::shared_ptr< SUBSET > | PSubset |
| shared pointer to the feature subset being trained/evaluated | |
| typedef DATAACCESSOR::PPattern | PPattern |
| one data sample as exposed by DATAACCESSOR | |
| Public Types inherited from FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying train/test blocks | |
| typedef std::shared_ptr< SUBSET > const | PSubset |
| shared pointer to the (fixed, non-reassignable) feature subset being evaluated | |
| typedef DATAACCESSOR::PPattern | PPattern |
| one data sample as exposed by DATAACCESSOR (a raw pointer to its feature vector) | |
Public Member Functions | |
| void | set_parameter_C (const REALTYPE c) |
| sets the SVM regularization parameter C (box constraint upper bound U under L1-loss); default 1 | |
| void | set_parameter_gamma (const REALTYPE g) |
| RBF width on standardized features; 0 = auto (1/d), which is the default. | |
| void | set_l2_loss (const bool l2) |
| false = hinge (C-SVC correspondence, default), true = squared hinge | |
| void | set_max_iter (const unsigned int mi) |
| cap on full coordinate sweeps; default 1000 | |
| void | set_tolerance (const REALTYPE t) |
| max |projected gradient| sweep-stopping threshold; default 0.1 | |
| REALTYPE | get_parameter_C () const |
| returns the configured C | |
| REALTYPE | get_parameter_gamma () const |
| the configured value (0 = auto 1/d until set explicitly) | |
| void | initialize (const PDataAccessor da) |
| records data shape, allocates the index buffer | |
| bool | optimize_parameters (const PDataAccessor da, const PSubset sub, const int max_points=100, const int max_throws=100, const double lgC_min=-5, const double lgC_max=9, const double lggamma_min=-15, const double lggamma_max=3, std::ostream &os=std::cout) |
| bool | mean_cv_accuracy (const PDataAccessor da, const PSubset sub, RETURNTYPE &mean) |
| train+test over the accessor's split loop (optimize_parameters' evaluation) | |
| virtual bool | classify (DIMTYPE &cls, const PPattern &pattern) override |
| virtual bool | classify_scores (std::vector< RETURNTYPE > &scores, const PPattern &pattern) override |
| virtual bool | train (const PDataAccessor da, const PSubset sub) override |
| Trains the RBF-kernel SVM: buffers the subset index, standardizes the design (dense_train_tools.hpp), precomputes the N x N kernel matrix when it fits within KERNEL_BUDGET_ENTRIES (otherwise kernel_row() recomputes rows on demand), solves one dual coordinate-descent problem per one-vs-rest model (solve_dual(), FIXED cyclic order), then compacts the trained state to the support vectors – patterns with a nonzero dual coefficient in ANY model – into _sv/_beta. Returns false only when the split has no training data (N==0); a subset/data shape mismatch is an assertion failure, not a bool return. | |
| virtual std::ostream & | print (std::ostream &os) const override |
| writes a human-readable identification of the object; base default writes nothing | |
| Public Member Functions inherited from FST::Clonable_Impl< Classifier_RBF_SVM< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >, Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > > | |
| Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | clone () const override |
| dispatches to the DEEP_KIND mechanism (default CLONE_DEEP: Derived's copy-constructor) | |
| Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | sharing_clone () const override |
| dispatches to the SHARING_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | stateless_clone () const override |
| dispatches to the STATELESS_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Public Member Functions inherited from FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | |
| virtual bool | train (const PDataAccessor da, const PSubset sub)=0 |
| learns from designated training part of data | |
| virtual bool | test (RETURNTYPE &result, const PDataAccessor da) |
| virtual bool | test_confusion (std::vector< RETURNTYPE > &confusion, DIMTYPE &classes, const PDataAccessor da) |
| virtual bool | test_scores (std::vector< std::pair< RETURNTYPE, DIMTYPE > > &scores, const PDataAccessor da) |
| virtual bool | test_scores_matrix (std::vector< RETURNTYPE > &scores, std::vector< DIMTYPE > &labels, DIMTYPE &classes, const PDataAccessor da) |
| virtual bool | test_metric (RETURNTYPE &result, const PDataAccessor da, const Metric_Spec< RETURNTYPE > &spec) |
| Public Member Functions inherited from FST::Clonable | |
| bool | is_clone () const |
| bool | is_sharing () const |
| true if this instance is a sharing_clone() result (referencing, not owning, the source's structures) | |
| bool | is_sharing_clone () const |
| true if this instance is BOTH a clone and sharing – i.e. specifically a sharing_clone() result, not a clone()/stateless_clone() one | |
Protected Member Functions | |
| REALTYPE | kernel_value (const REALTYPE *a, const REALTYPE *b) const |
The penalized-bias RBF kernel K'(a,b) = exp(-gamma_eff*||a-b||^2) + 1 over the current _subfeatures standardized coordinates. a and b must each point at (at least) _subfeatures contiguous standardized values in subset order, e.g. rows of _Z/_sv or the classify_scores() scratch – never raw, unstandardized pattern data. | |
| const REALTYPE * | kernel_row (const std::size_t i, const std::size_t N) |
Row i of the N x N kernel matrix over the N training patterns in _Z. When _K was precomputed (the within-budget path) returns a pointer straight into it; otherwise recomputes the row into the _krow scratch buffer and returns that instead – in that mode the returned pointer is only valid until the next kernel_row() call, since _krow is reused. N must match _Z's row count (the caller's training-set size). | |
| void | solve_dual (REALTYPE *beta, const DIMTYPE positive_class) |
One one-vs-rest kernel dual coordinate-descent run: patterns of class positive_class are the +1 side, all others the -1 side. Writes the N dual coefficients alpha_i*y_i into beta, which must have room for N = _y.size() entries. Requires _Z/_y/_gamma_eff and the kernel state (_K or _krow) to be set up by train(); uses _alpha and _s as scratch. Stops when the largest projected gradient of a sweep falls below _tol, or after _max_iter sweeps (no convergence failure is reported – an unconverged model is simply less accurate). | |
| DIMTYPE | model_count () const |
| number of one-vs-rest models actually trained: 1 for two-class data (the single model scores both sides), _classes otherwise | |
| Protected Member Functions inherited from FST::Clonable | |
| void | set_cloned (const bool cloned=true) |
| marks/unmarks this instance as a clone; call from clone()/stateless_clone() overrides (Clonable_Impl does this automatically) | |
| void | set_sharing (const bool sharing=true) |
| marks/unmarks this instance as sharing (see is_sharing()) | |
| void | set_sharing_cloned (const bool cloned=true, const bool sharing=true) |
| sets both flags at once; call from sharing_clone() overrides (Clonable_Impl does this automatically) | |
Protected Attributes | |
| REALTYPE | _C |
| regularization parameter, see set_parameter_C() | |
| REALTYPE | _gamma |
| configured RBF gamma; 0 = auto: 1/d per train() (the effective value actually used is _gamma_eff) | |
| bool | _l2loss |
| false = hinge loss (default), true = squared hinge | |
| unsigned int | _max_iter |
| cap on full coordinate sweeps in solve_dual() | |
| REALTYPE | _tol |
| max |projected gradient| sweep-stopping threshold | |
| DIMTYPE | _classes |
| class count, set by initialize() | |
| DIMTYPE | _features |
| raw (full, unnarrowed) feature count, set by initialize() | |
| DIMTYPE | _subfeatures |
| d = current subset size | |
| std::vector< DIMTYPE > | _index |
| subset position -> raw feature index (first d entries valid) | |
| std::vector< REALTYPE > | _mean |
| standardization shift per subset position | |
| std::vector< REALTYPE > | _scale |
| standardization scale per subset position (1 for constant features) | |
| REALTYPE | _gamma_eff |
| gamma actually used by the trained model (resolves _gamma's 0=auto to 1/d) | |
| IDXTYPE | _sv_count |
| support vectors kept (nonzero dual coefficient in ANY model) | |
| std::vector< REALTYPE > | _sv |
| sv_count x d standardized support-vector values | |
| std::vector< REALTYPE > | _beta |
| models x sv_count dual coefficients alpha_i*y_i; two-class data holds ONE model | |
| std::vector< REALTYPE > | _Z |
| N x d standardized design (no bias coordinate — the +1 kernel offset carries it). | |
| std::vector< DIMTYPE > | _y |
| N training labels. | |
| std::vector< REALTYPE > | _alpha |
| N dual variables of the model currently being trained (solve_dual() scratch). | |
| std::vector< REALTYPE > | _s |
| N maintained margin sums s_k = sum_j alpha_j y_j K'_jk. | |
| std::vector< REALTYPE > | _K |
| N x N kernel matrix K' (only when within budget, else empty – see KERNEL_BUDGET_ENTRIES). | |
| std::vector< REALTYPE > | _krow |
| kernel-row scratch for the above-budget mode (filled by kernel_row()) | |
| std::vector< REALTYPE > | _cs_x |
| classify_scores() per-pattern scratch: the standardized query pattern (kept as a member to avoid per-pattern allocation) | |
| std::vector< REALTYPE > | _cs_kv |
| classify_scores() per-pattern scratch: kernel value against each support vector | |
| std::vector< RETURNTYPE > | _cs_sc |
| classify() score scratch | |
| std::vector< REALTYPE > | _beta_full |
| models x N pre-compaction dual coefficients (solve_dual() output before the support-vector compaction in train()); kept allocated as scratch, the trained model itself is _sv/_beta | |
Detailed Description
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
class FST::Classifier_RBF_SVM< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
class FST::Classifier_RBF_SVM< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
Dependency-free RBF kernel SVM trained by kernel dual coordinate descent (implemented from scratch, no LibSVM code; C-SVC with the RBF kernel only, deliberately NOT a LibSVM replacement: no nu-variants, no SVR, no one-class, no probability estimates, no shrinking).
The solver is the Classifier_Linear_SVM structure kernelized via the PENALIZED-BIAS formulation: the kernel is offset by a constant, K'(x,z) = exp(-gamma*||x-z||^2) + 1, the kernel analogue of the appended constant coordinate (LIBLINEAR's -B 1 convention) - this removes the equality constraint that otherwise forces two-variable SMO, so the dual stays a box-constrained problem solved coordinate-wise in FIXED CYCLIC order: fully deterministic and RNG-free, so a fixed seed and any thread count give identical results (the fst_rand stream is never touched). The margin sums s_k = sum_j alpha_j y_j K'_jk are maintained incrementally, so one gradient check costs O(1) and one alpha update costs O(N) given the kernel row. The N x N kernel matrix is precomputed when it fits a fixed memory budget (shared by all one-vs-rest models); above the budget, kernel rows are recomputed on demand - slower, still exact and deterministic. L1-loss (hinge; the C-SVC correspondence, default) or L2-loss (squared hinge) via the diagonal shift, exactly as in the linear solver. Features are standardized internally per split like the logistic-regression classifier; gamma defaults to 1/d on the standardized features (0 = auto). Deliberately a SIBLING of Classifier_Linear_SVM, not a refactor - the linear solver keeps its kernel-free fast path.
Multiclass = one-vs-rest with K dual solves over the SAME kernel matrix; two-class data trains ONE model (class index 0 = +1 side) and derives both scores from its single decision value. After training the model is compacted to the support vectors (patterns with a nonzero dual coefficient in ANY model); classify() takes the argmax of the per-class decision values (first maximum wins) and classify_scores() exposes them for the ranking metrics (AUC). The bias lives inside the +1 kernel offset - sum_i beta_i acts as the intercept, no separate term.
Results are NOT bit-comparable to LibSVM at matched C/gamma (different solver, penalized vs. exact bias, internal standardization) - the correspondence bar is near-identical accuracy, by design.
Member Function Documentation
◆ classify()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
argmax of the per-class decision values; the first maximum wins. Both this and classify_scores() require a successful train() first – with asserts disabled an untrained model has no support vectors and silently scores every class 0, i.e. classifies everything as class 0.
Implements FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ classify_scores()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
per-class decision values (the quantity classify() maximizes) for ranking metrics such as AUC; higher means more evidence for that class. For two-class data the two entries are the single model's decision value and its negation.
Reimplemented from FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ optimize_parameters()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
| bool FST::Classifier_RBF_SVM< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >::optimize_parameters | ( | const PDataAccessor | da, |
| const PSubset | sub, | ||
| const int | max_points = 100, | ||
| const int | max_throws = 100, | ||
| const double | lgC_min = -5, | ||
| const double | lgC_max = 9, | ||
| const double | lggamma_min = -15, | ||
| const double | lggamma_max = 3, | ||
| std::ostream & | os = std::cout ) |
C/gamma random search mirroring Classifier_LIBSVM::optimize_parameters: space-filling candidate choice - each of max_points points is the best of max_throws draws, maximizing its minimum log-space distance to the already-evaluated points, distances weighed by those points' accuracy to repel from bad regions - evaluated by mean test accuracy over the accessor's split loop; the best tested pair is set on exit. The lg* bounds are NATURAL logarithms (a candidate is exp(uniform(min,max))), as in the LibSVM twin. Returns false as soon as a train()/test() fails. All randomness comes from fst_rand on the CALLING (master) thread, so a fixed seed reproduces the search exactly; training itself stays RNG-free.
- Note
- This always leaves an EXPLICIT gamma set on the object, so the 0 = auto (1/d) setting does not survive a call: re-set gamma to 0 to restore it.
- The trained model on return is the one from the last candidate evaluated, not from the best one - call train() again before classify()/test().
◆ print()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
inlineoverridevirtual |
writes a human-readable identification of the object; base default writes nothing
Reimplemented from FST::Clonable.
◆ train()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Trains the RBF-kernel SVM: buffers the subset index, standardizes the design (dense_train_tools.hpp), precomputes the N x N kernel matrix when it fits within KERNEL_BUDGET_ENTRIES (otherwise kernel_row() recomputes rows on demand), solves one dual coordinate-descent problem per one-vs-rest model (solve_dual(), FIXED cyclic order), then compacts the trained state to the support vectors – patterns with a nonzero dual coefficient in ANY model – into _sv/_beta. Returns false only when the split has no training data (N==0); a subset/data shape mismatch is an assertion failure, not a bool return.
- Note
- Cost and memory jump at N*N > KERNEL_BUDGET_ENTRIES: below it the kernel matrix is built once (N*N reals) and every sweep reads it; above it each alpha update recomputes a kernel row in O(N*d), which is markedly slower but bounded in memory.
The documentation for this class was generated from the following file:
- /Users/psms/dev/devtest1/_src_criteria/classifier_rbf_svm.hpp
Generated by
 1.17.0