Loading...
Searching...
No Matches
Classes |
Public Types |
Public Member Functions |
Protected Types |
Protected Member Functions |
Protected Attributes |
Private Member Functions |
Private Attributes |
List of all members
FST::Classifier_LIBSVM< RETURNTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR > Class Template Reference
Wraps external Support Vector Machine implementation (in LibSVM) to serve as FST4 classifier. More...
#include <classifier_svm.hpp>
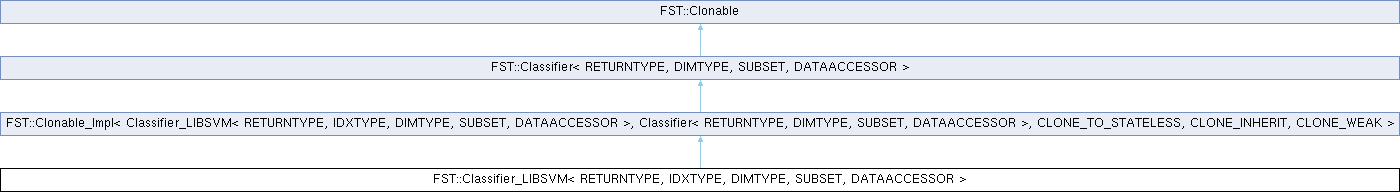
Inheritance diagram for FST::Classifier_LIBSVM< RETURNTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >:
Classes | |
| class | ParameterSet |
| Nested class to hold parameter candidates in the course of optimize_parameters() run. More... | |
Public Types | |
| typedef Clonable_Impl< Classifier_LIBSVM, Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >, CLONE_TO_STATELESS, CLONE_INHERIT, CLONE_WEAK > | parent_impl |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying train/test blocks | |
| typedef std::shared_ptr< SUBSET > const | PSubset |
| shared pointer to the (fixed) feature subset being trained/evaluated | |
| typedef DATAACCESSOR::PPattern | PPattern |
| one data sample as exposed by DATAACCESSOR | |
| Public Types inherited from FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying train/test blocks | |
| typedef std::shared_ptr< SUBSET > const | PSubset |
| shared pointer to the (fixed, non-reassignable) feature subset being evaluated | |
| typedef DATAACCESSOR::PPattern | PPattern |
| one data sample as exposed by DATAACCESSOR (a raw pointer to its feature vector) | |
Public Member Functions | |
| void | initialize (const PDataAccessor da) |
Must be called (once, or again after a dataset-shape change) before train()/test(). Discards any previously allocated buffers (cleanup()), records the new dataset shape (pattern/class/feature counts) from da, then pre-allocates the LibSVM problem/parameter transfer buffers sized to it (allocate()). | |
| void | set_parameter_C (double newC) |
| sets the LibSVM regularization parameter C | |
| void | set_parameter_gamma (double newgamma) |
| sets the LibSVM kernel gamma (RBF/POLY/SIGMOID) | |
| void | set_parameter_coef0 (double newcoef0) |
| sets the LibSVM kernel coef0 (POLY/SIGMOID) | |
| void | set_kernel_type (int kernel_type) |
| LINEAR/POLY/RBF/SIGMOID – see svm.h for admissible values. | |
| double | get_parameter_C () const |
| current LibSVM regularization parameter C | |
| double | get_parameter_gamma () const |
| current LibSVM kernel gamma (RBF/POLY/SIGMOID) | |
| double | get_parameter_coef0 () const |
| current LibSVM kernel coef0 (POLY/SIGMOID) | |
| int | get_kernel_type () const |
| see svm.h for admissible values | |
| virtual bool | classify (DIMTYPE &cls, const PPattern &pattern) override |
| virtual bool | classify_scores (std::vector< RETURNTYPE > &scores, const PPattern &pattern) override |
| virtual bool | train (const PDataAccessor da, const PSubset sub) override |
| virtual bool | test (RETURNTYPE &result, const PDataAccessor da) override |
| bool | optimize_parameters (const PDataAccessor da, const PSubset sub, const int max_points=100, const int max_throws=100, const double lgC_min=-5, const double lgC_max=9, const double lggamma_min=-15, const double lggamma_max=3, const double lgcoef0_min=-2, const double lgcoef0_max=5, std::ostream &os=std::cout) |
| Searches for better SVM hyperparameters C, gamma and coef0 and adopts the best set found. | |
| virtual std::ostream & | print (std::ostream &os) const override |
| writes a human-readable identification of the object; base default writes nothing | |
| Public Member Functions inherited from FST::Clonable_Impl< Classifier_LIBSVM< RETURNTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >, Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >, CLONE_TO_STATELESS, CLONE_INHERIT, CLONE_WEAK > | |
| Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | clone () const override |
| dispatches to the DEEP_KIND mechanism (default CLONE_DEEP: Derived's copy-constructor) | |
| Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | sharing_clone () const override |
| dispatches to the SHARING_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | stateless_clone () const override |
| dispatches to the STATELESS_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Public Member Functions inherited from FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | |
| virtual bool | test_confusion (std::vector< RETURNTYPE > &confusion, DIMTYPE &classes, const PDataAccessor da) |
| virtual bool | test_scores (std::vector< std::pair< RETURNTYPE, DIMTYPE > > &scores, const PDataAccessor da) |
| virtual bool | test_scores_matrix (std::vector< RETURNTYPE > &scores, std::vector< DIMTYPE > &labels, DIMTYPE &classes, const PDataAccessor da) |
| virtual bool | test_metric (RETURNTYPE &result, const PDataAccessor da, const Metric_Spec< RETURNTYPE > &spec) |
| Public Member Functions inherited from FST::Clonable | |
| bool | is_clone () const |
| bool | is_sharing () const |
| true if this instance is a sharing_clone() result (referencing, not owning, the source's structures) | |
| bool | is_sharing_clone () const |
| true if this instance is BOTH a clone and sharing – i.e. specifically a sharing_clone() result, not a clone()/stateless_clone() one | |
Protected Types | |
| typedef std::list< ParameterSet > | PARAMSETLIST |
| the growing list of parameter candidates evaluated so far, in evaluation order | |
Protected Member Functions | |
| void | allocate () |
| void | cleanup () |
| Protected Member Functions inherited from FST::Clonable | |
| void | set_cloned (const bool cloned=true) |
| marks/unmarks this instance as a clone; call from clone()/stateless_clone() overrides (Clonable_Impl does this automatically) | |
| void | set_sharing (const bool sharing=true) |
| marks/unmarks this instance as sharing (see is_sharing()) | |
| void | set_sharing_cloned (const bool cloned=true, const bool sharing=true) |
| sets both flags at once; call from sharing_clone() overrides (Clonable_Impl does this automatically) | |
Protected Attributes | |
| IDXTYPE | _all_patterns |
| total pattern count across all classes, set by initialize() | |
| DIMTYPE | _classes |
| class count, set by initialize() | |
| DIMTYPE | _features |
| raw (full, unnarrowed) feature count, set by initialize() | |
| struct svm_problem | problem |
| LibSVM training data (problem.x/y), rebuilt by train() from the designated TRAIN blocks. | |
| struct svm_parameter | parameters |
| LibSVM training parameters (C, gamma, kernel_type, ...) – see set_parameter_*()/set_kernel_type(). | |
| struct svm_model * | model |
| the trained LibSVM model, or nullptr before the first successful train() | |
| struct svm_node * | onepattern |
| single-pattern LibSVM transfer buffer, filled by fill_onepattern() for classify()/classify_scores() | |
| bool | svm_class_weighing |
| vestigial class-weighing switch: set false by the constructor and never read – allocate() unconditionally forces parameters.nr_weight=0 regardless of this flag | |
Private Member Functions | |
| Classifier_LIBSVM (const Classifier_LIBSVM &csvm, int) | |
| Weak copy-constructor backing stateless_clone() (see parent_impl above): copies configuration (parameters, shape counters, svm_class_weighing, the narrowing _index) but deliberately NOT the trained LibSVM model/problem structures – it allocate()s fresh, empty transfer buffers instead. The resulting clone is therefore UNTRAINED; classify()/ test() throw until train() is called on it. | |
| void | fill_onepattern (const PPattern &pattern) |
| transfers the pattern's nonzero selected features into onepattern (the shared classify()/classify_scores() transfer loop) | |
Private Attributes | |
| friend | parent_impl |
| std::unique_ptr< DIMTYPE[]> | _index |
| subset position -> raw feature index map, filled by train() from sub->selected_features(); regrown on demand | |
| DIMTYPE | _subfeatures |
| current subset size (number of valid entries in _index[]), set by train() | |
| std::vector< double > | _dec |
Detailed Description
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
class FST::Classifier_LIBSVM< RETURNTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
class FST::Classifier_LIBSVM< RETURNTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
Wraps external Support Vector Machine implementation (in LibSVM) to serve as FST4 classifier.
- Note
- clone() yields an UNTRAINED clone (LibSVM model structures cannot be deep-copied); using an untrained clone fails loudly in classify()/test() - call train() first.
- LibSVM is NOT distributed with FST4. Obtain svm.cpp and svm.h (version 3.37, or any version compatible with the public LibSVM API used here) from the LibSVM site and place them into ./libsvm/ before building anything that includes this header; libsvm/readme.txt in the FST4 distribution states the exact steps.
- Warning
- LIBSVM especially with LINEAR kernel seems to have occassional problems with certain C values on certain datasets and may freeze. (Other kernels are more stable but not completely immune to this problem.) This is a problem outside FST4. Classifier_Linear_SVM and Classifier_RBF_SVM are FST4's own, dependency-free alternatives.
Member Typedef Documentation
◆ parent_impl
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
| typedef Clonable_Impl<Classifier_LIBSVM,Classifier<RETURNTYPE,DIMTYPE,SUBSET,DATAACCESSOR>,CLONE_TO_STATELESS,CLONE_INHERIT,CLONE_WEAK> FST::Classifier_LIBSVM< RETURNTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >::parent_impl |
parent_impl: clone() forwards to stateless_clone() (LibSVM model structures cannot be cloned, so clones are UNTRAINED - which is what makes threaded wrapper usage possible at all, as the wrapper always train()s a clone before using it); stateless_clone() uses the weak copy-constructor; sharing_clone() throws in Classifier. Using an untrained clone fails loudly in classify()/test().
Member Function Documentation
◆ allocate()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
protected |
Pre-allocates the svm_problem/svm_parameter transfer buffers sized to the current _all_patterns/_classes/_features (the caller – initialize() or the weak copy-constructor – must set these first). Throws fst_error (via cleanup()) on malloc failure.
◆ classify()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
classifies pattern, returns the respective class index in cls. Throws fst_error when no model has been trained yet (in particular on a fresh clone, which never inherits the trained state).
Implements FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ classify_scores()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
LibSVM decision values for ranking metrics (AUC): binary = signed decision value, K>2 = per-class one-vs-one aggregation; deterministic, unlike LibSVM's probability mode. Throws fst_error when untrained; returns false when the trained model's class labels cannot be mapped onto [0,classes).
Reimplemented from FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ cleanup()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
protected |
Frees every LibSVM-related buffer and resets the shape counters to 0; idempotent (each pointer is individually guarded) – safe to call from allocate()'s failure handler, initialize(), and the destructor.
◆ optimize_parameters()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
| bool FST::Classifier_LIBSVM< RETURNTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >::optimize_parameters | ( | const PDataAccessor | da, |
| const PSubset | sub, | ||
| const int | max_points = 100, | ||
| const int | max_throws = 100, | ||
| const double | lgC_min = -5, | ||
| const double | lgC_max = 9, | ||
| const double | lggamma_min = -15, | ||
| const double | lggamma_max = 3, | ||
| const double | lgcoef0_min = -2, | ||
| const double | lgcoef0_max = 5, | ||
| std::ostream & | os = std::cout ) |
Searches for better SVM hyperparameters C, gamma and coef0 and adopts the best set found.
A space-filling random search, not a grid: max_points candidate parameter sets are evaluated one after another; each is chosen by drawing max_throws random candidates and keeping the one whose distance to the already-evaluated candidates (normalized per axis, weighted by their accuracy so that the neighbourhood of bad candidates is explored less) is largest. A candidate is evaluated by train()+test() over the ENTIRE split loop of da with the fixed feature subset sub; its value is the mean accuracy over the splits. The current parameter values are evaluated first and take part in the competition.
- Parameters
-
da data accessor; initialize() must have been called for it. Its split loop is traversed once per candidate, so the cost is (max_points+1) * splits * (train+test). sub the feature subset to optimize for; must be non-empty and stays fixed. max_points number of candidate parameter sets to evaluate (>0). max_throws number of random draws per candidate to choose from (>0); larger values spread the candidates more evenly at negligible cost (no training is involved). lgC_min,lgC_max,lggamma_min,lggamma_max,lgcoef0_min,lgcoef0_max search bounds, given as NATURAL logarithms of the parameter despite the "lg" in the names: a candidate is exp(uniform(min,max)). The defaults therefore span C in [e^-5,e^9], gamma in [e^-15,e^3], coef0 in [e^-2,e^5]. Each max must exceed its min. gamma is only meaningful for RBF/POLY/SIGMOID and coef0 only for POLY/SIGMOID – the unused ones are still drawn and set, but they do not enter the candidate distance and do not affect the model. os stream the progress report is written to (one line per candidate, plus a before/after summary); pass a null stream to silence it.
- Returns
- true when the search completed; false as soon as a train() or test() call fails, in which case the object keeps the parameters of the candidate that was being evaluated.
- Note
- On success the object's C, gamma and coef0 are left set to the best candidate, but the trained model is still the one from the LAST candidate evaluated – call train() again before classify()/test() to use the optimized parameters.
- Randomness comes from fst_rand(), so a given seed reproduces the whole search. Not reentrant (it uses a member iterator), and it must not run concurrently on one object.
- Warning
- LIBSVM LINEAR kernel seems to have problems with certain C values on certain datasets. If the optimization process seemingly freezes, try narrower lgC_min and lgC_max. Especially the lower bound seems important to be increased.
◆ print()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
inlineoverridevirtual |
writes a human-readable identification of the object; base default writes nothing
Reimplemented from FST::Clonable.
◆ test()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
estimates accuracy (fraction of correctly classified patterns) over the designated TEST part of the data, using the subset train() was last called with. Throws fst_error when untrained.
Reimplemented from FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ train()
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
learns from the designated TRAIN part of the data, restricted to the features in sub. Requires a preceding initialize() for the same dataset shape. Returns false when LibSVM returns no model; throws fst_error on transfer failures (the object is cleanup()'d first).
Implements FST::Classifier< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
Member Data Documentation
◆ _dec
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
private |
classify_scores() one-vs-one decision-value scratch (member to avoid per-pattern allocation)
◆ parent_impl
template<class RETURNTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
private |
grants Clonable_Impl access to the weak copy-constructor
The documentation for this class was generated from the following file:
- /Users/psms/dev/devtest1/_src_criteria/classifier_svm.hpp
Generated by
 1.17.0