Loading...
Searching...
No Matches
Public Types |
Public Member Functions |
Protected Member Functions |
Protected Attributes |
List of all members
FST::Regressor_Ridge< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR > Class Template Reference
Closed-form ridge regression (L2-regularized least squares) for wrapper-based feature selection. More...
#include <regressor_ridge.hpp>
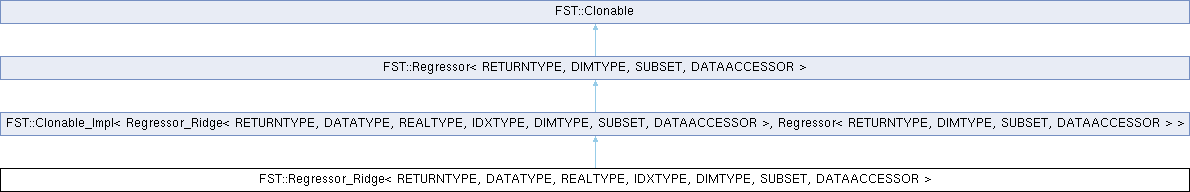
Inheritance diagram for FST::Regressor_Ridge< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >:
Public Types | |
| typedef Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | parent |
| the immediate abstract base | |
| typedef Clonable_Impl< Regressor_Ridge, parent > | parent_impl |
| implements clone() via the (implicit, member-wise) copy-constructor - all members are value-semantic | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying train/test blocks | |
| typedef std::shared_ptr< SUBSET > | PSubset |
| shared pointer to the feature subset being trained/evaluated on | |
| typedef DATAACCESSOR::PPattern | PPattern |
| one data sample as exposed by DATAACCESSOR (a raw pointer to its feature vector) | |
| Public Types inherited from FST::Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | |
| typedef std::shared_ptr< DATAACCESSOR > | PDataAccessor |
| shared pointer to the data accessor supplying train/test blocks | |
| typedef std::shared_ptr< SUBSET > const | PSubset |
| shared pointer to the (fixed, non-reassignable) feature subset being evaluated | |
| typedef DATAACCESSOR::PPattern | PPattern |
| one data sample as exposed by DATAACCESSOR (a raw pointer to its feature vector) | |
Public Member Functions | |
| void | set_lambda (const REALTYPE l) |
| void | set_dependent_index (const DIMTYPE depvaridx) |
| Chooses the dependent variable: a raw data column index, or any out-of-range value (the (DIMTYPE)-1 default) to predict the class label instead. | |
| void | initialize (const PDataAccessor da) |
| records data shape, allocates the index buffer | |
| virtual bool | predict (RETURNTYPE &depvar, const PPattern &pattern) override |
| virtual bool | train (const PDataAccessor da, const PSubset sub) override |
| virtual bool | test (RETURNTYPE &result, const PDataAccessor da) override |
| Scores the designated test data with the regressor's own default measure, oriented higher-is-better (a hit rate under the class-label convention, a negated prediction error otherwise). Returns false if the test part is empty or predict() failed. | |
| virtual bool | test_metric (RETURNTYPE &result, const PDataAccessor da, const Metric_Spec< RETURNTYPE > &spec) override |
| virtual std::ostream & | print (std::ostream &os) const override |
| writes a human-readable identification of the object; base default writes nothing | |
| Public Member Functions inherited from FST::Clonable_Impl< Regressor_Ridge< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >, Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > > | |
| Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | clone () const override |
| dispatches to the DEEP_KIND mechanism (default CLONE_DEEP: Derived's copy-constructor) | |
| Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | sharing_clone () const override |
| dispatches to the SHARING_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > * | stateless_clone () const override |
| dispatches to the STATELESS_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Public Member Functions inherited from FST::Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR > | |
| virtual bool | train (const PDataAccessor da, const PSubset sub)=0 |
| Regressor * | sharing_clone () const override |
| Regressor * | stateless_clone () const override |
| Public Member Functions inherited from FST::Clonable | |
| bool | is_clone () const |
| bool | is_sharing () const |
| true if this instance is a sharing_clone() result (referencing, not owning, the source's structures) | |
| bool | is_sharing_clone () const |
| true if this instance is BOTH a clone and sharing – i.e. specifically a sharing_clone() result, not a clone()/stateless_clone() one | |
Protected Member Functions | |
| bool | dependent_from (const PPattern &pat, const DIMTYPE cls, REALTYPE &dep) const |
| bool | collect_predictions (const PDataAccessor da, std::vector< std::pair< RETURNTYPE, RETURNTYPE > > &pairs) |
| the shared test-part (dependent,prediction) enumeration behind test() and test_metric() | |
| Protected Member Functions inherited from FST::Clonable | |
| void | set_cloned (const bool cloned=true) |
| marks/unmarks this instance as a clone; call from clone()/stateless_clone() overrides (Clonable_Impl does this automatically) | |
| void | set_sharing (const bool sharing=true) |
| marks/unmarks this instance as sharing (see is_sharing()) | |
| void | set_sharing_cloned (const bool cloned=true, const bool sharing=true) |
| sets both flags at once; call from sharing_clone() overrides (Clonable_Impl does this automatically) | |
Protected Attributes | |
| REALTYPE | _lambda |
| L2 penalty weight; set by set_lambda(). | |
| DIMTYPE | _dep_var_idx |
| dependent-variable data column, or an out-of-range sentinel ((DIMTYPE)-1 by default) meaning "use the class label"; set by set_dependent_index() | |
| DIMTYPE | _features |
| raw feature count recorded by initialize(), for sizing _index and for dependent_from()'s column-vs-label test | |
| DIMTYPE | _subfeatures |
| d = features used by the current model (dependent column excluded) | |
| std::vector< DIMTYPE > | _index |
| subset position -> raw feature index (first d entries valid) | |
| std::vector< REALTYPE > | _mean |
| standardization shift per subset position | |
| std::vector< REALTYPE > | _scale |
| standardization scale per subset position (1 for constant features) | |
| std::vector< REALTYPE > | _w |
| d weights + bias at [d] | |
| std::vector< REALTYPE > | _A |
| (d+1)x(d+1) normal-equation matrix, row-major | |
| std::vector< REALTYPE > | _b |
| d+1 right-hand side | |
| std::vector< REALTYPE > | _Z |
| N x (d+1) standardized design. | |
| std::vector< REALTYPE > | _yv |
| N dependent values. | |
Detailed Description
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
class FST::Regressor_Ridge< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
class FST::Regressor_Ridge< RETURNTYPE, DATATYPE, REALTYPE, IDXTYPE, DIMTYPE, SUBSET, DATAACCESSOR >
Closed-form ridge regression (L2-regularized least squares) for wrapper-based feature selection.
Solves the L2-regularized normal equations by Cholesky factorization on the internally standardized design (per-split feature mean/scale, like the logistic-regression classifier; the bias coordinate is unpenalized). Entirely deterministic and RNG-free - like logreg, the result depends on neither the seed nor the thread count.
NOTE on the scale of lambda: the accumulated normal equations are divided by the training pattern count N BEFORE the penalty is added, so the system actually solved is
(Z^T Z / N + lambda*I) w = Z^T y / N,
equivalent to the textbook (Z^T Z + N*lambda*I) w = Z^T y. lambda is therefore a PER-SAMPLE penalty: its useful magnitude does not change when the training set grows, unlike the textbook parameter, but it is not numerically interchangeable with one quoted for the unscaled formulation.
Dependent-variable convention MATCHES Regressor_Weighted_Neighbours (the wrapper-regressor pipeline): set_dependent_index(idx) selects a data column - which is then EXCLUDED from the model's features, so a subset containing it is fitted with one feature fewer than it holds; any out-of-range index (the (DIMTYPE)-1 sentinel, which is the default) selects the class label - "regression simulating classification". test() likewise mirrors the weighted-neighbours conventions (label mode: fraction of predictions within 0.5 of the label; column mode: negated mean absolute error), so the two regressors' test() values are directly comparable; for feature selection the regression metrics (R^2, negated RMSE/MAE) offered through test_metric() are the more natural choice, and the fst4 CLI defaults this regressor to R^2.
Member Function Documentation
◆ dependent_from()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
inlineprotected |
Resolves the dependent value for one pattern: pat[_dep_var_idx] when _dep_var_idx names a valid raw feature column, otherwise cls (the "regression simulating classification" convention shared with Regressor_Weighted_Neighbours). It cannot fail; the bool return exists only so a guarded failure mode could be added without changing the call sites.
◆ predict()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
evaluates the trained linear model (standardized weights + bias) at pattern. Requires a successful train(): with assertions disabled an untrained model reads empty weight vectors.
Implements FST::Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ print()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
inlineoverridevirtual |
writes a human-readable identification of the object; base default writes nothing
Reimplemented from FST::Clonable.
◆ set_dependent_index()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
inline |
Chooses the dependent variable: a raw data column index, or any out-of-range value (the (DIMTYPE)-1 default) to predict the class label instead.
- Warning
- A chosen column is REMOVED from the model's features - a feature must not help predict itself. A d-feature subset containing it is therefore fitted on d-1 features, and a subset consisting of it alone makes train() fail.
◆ set_lambda()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
inline |
sets the L2 penalty weight applied to the (unpenalized-bias) normal equations; default 0.01. Per-sample units – see the class documentation
◆ test()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Scores the designated test data with the regressor's own default measure, oriented higher-is-better (a hit rate under the class-label convention, a negated prediction error otherwise). Returns false if the test part is empty or predict() failed.
Implements FST::Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ test_metric()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
evaluates the designated test data under the given regression metric (r2/neg-rmse/neg-mae); the default spec is served by test() itself. Classification metrics do not apply to a regression stack and make this return false. The dependent-variable convention is the concrete regressor's - see the class documentation.
Reimplemented from FST::Regressor< RETURNTYPE, DIMTYPE, SUBSET, DATAACCESSOR >.
◆ train()
template<class RETURNTYPE, typename DATATYPE, typename REALTYPE, typename IDXTYPE, typename DIMTYPE, class SUBSET, class DATAACCESSOR>
|
overridevirtual |
Fits sub's features (excluding the dependent column, if selected) by Cholesky-solving the L2-regularized normal equations on the internally standardized design; returns false if the subset holds only the dependent column, or if the Gram-plus-ridge matrix is not solvable.
The documentation for this class was generated from the following file:
- /Users/psms/dev/devtest1/_src_criteria/regressor_ridge.hpp
Generated by
 1.17.0