Loading...
Searching...
No Matches
Public Types |
Public Member Functions |
Protected Types |
Protected Member Functions |
List of all members
FST::Data_Splitter_Resub< INTERVALCONTAINER, IDXTYPE > Class Template Reference
Implements train/test data splitting: use all data both for training and then once more for testing. More...
#include <data_splitter_resub.hpp>
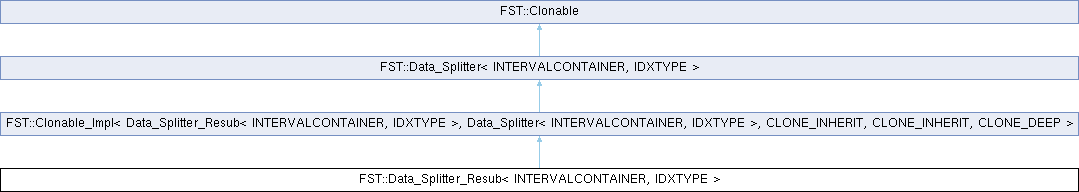
Inheritance diagram for FST::Data_Splitter_Resub< INTERVALCONTAINER, IDXTYPE >:
Public Types | |
| typedef Clonable_Impl< Data_Splitter_Resub, Data_Splitter< INTERVALCONTAINER, IDXTYPE >, CLONE_INHERIT, CLONE_INHERIT, CLONE_DEEP > | parent_impl |
| implements stateless_clone(); clone/sharing_clone throw in Data_Splitter | |
| Public Types inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| typedef std::shared_ptr< INTERVALCONTAINER > | PIntervaller |
| shared pointer to one class's list of train/test data intervals | |
Public Member Functions | |
| Data_Splitter_Resub (const Data_Splitter_Resub &dsp) | |
| copies configuration (this splitter is parameterless, so there is nothing else to copy) | |
| virtual IDXTYPE | getNoOfSplits () const override |
| virtual std::ostream & | print (std::ostream &os) const override |
| writes a human-readable identification of the splitter and its configuration; base default writes nothing | |
| Public Member Functions inherited from FST::Clonable_Impl< Data_Splitter_Resub< INTERVALCONTAINER, IDXTYPE >, Data_Splitter< INTERVALCONTAINER, IDXTYPE >, CLONE_INHERIT, CLONE_INHERIT, CLONE_DEEP > | |
| Data_Splitter< INTERVALCONTAINER, IDXTYPE > * | clone () const override |
| dispatches to the DEEP_KIND mechanism (default CLONE_DEEP: Derived's copy-constructor) | |
| Data_Splitter< INTERVALCONTAINER, IDXTYPE > * | sharing_clone () const override |
| dispatches to the SHARING_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Data_Splitter< INTERVALCONTAINER, IDXTYPE > * | stateless_clone () const override |
| dispatches to the STATELESS_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Public Member Functions inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| Data_Splitter (const Data_Splitter &dsp) | |
Deep-copies every class's TClassSplitter (own train/test interval lists, not shared with dsp). | |
| void | assign (const unsigned int _clsidx, const PIntervaller _train, const PIntervaller _test) |
Registers class _clsidx's train/test interval lists (growing csplit as needed); the caller retains ownership via the shared pointers. | |
| void | set_n (const unsigned int _clsidx, const IDXTYPE _n) |
Sets class _clsidx's pattern count, which getNoOfSplits() and the concrete prepare*/splitClass* hooks size their splits against (growing csplit as needed). | |
| IDXTYPE | get_n (const unsigned int _clsidx) const |
the pattern count previously set for class _clsidx via set_n() | |
| bool | makeFirstSplit () |
| Produces the first split: prepareFirstSplit(), then splitClassFirst() per class, then finishSplit(). | |
| bool | makeNextSplit () |
| Produces the next split: prepareNextSplit(), then splitClassNext() per class, then finishSplit(). | |
| Data_Splitter * | clone () const override |
| Data_Splitter * | sharing_clone () const override |
| Public Member Functions inherited from FST::Clonable | |
| bool | is_clone () const |
| bool | is_sharing () const |
| true if this instance is a sharing_clone() result (referencing, not owning, the source's structures) | |
| bool | is_sharing_clone () const |
| true if this instance is BOTH a clone and sharing – i.e. specifically a sharing_clone() result, not a clone()/stateless_clone() one | |
Protected Types | |
| typedef Data_Splitter< INTERVALCONTAINER, IDXTYPE > | TCC |
| alias for the Data_Splitter base, used by the per-class hook | |
| Protected Types inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| typedef std::shared_ptr< TClassSplitter > | PClassSplitter |
| shared pointer to one class's TClassSplitter | |
| typedef std::vector< PClassSplitter >::const_iterator | ClassIterator |
| iterator over csplit, as passed to the per-class splitClassFirst()/splitClassNext() hooks | |
Protected Member Functions | |
| virtual const char * | splitter_name () const override |
| class name, used in error messages | |
| virtual bool | prepareNextSplit () override |
| advance split-sequence state; false = no more splits | |
| virtual void | splitClassFirst (typename TCC::ClassIterator c, const unsigned int) override |
write first-split train/test intervals of class cidx (c is that class's entry in csplit) | |
| Protected Member Functions inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| void | assert_csplit () const |
| DEBUG-only: asserts csplit is non-empty and every class has n>0 and non-null train/test lists. | |
| virtual bool | prepareFirstSplit () |
| set up split-sequence state; false = no split can be made | |
| virtual void | splitClassNext (ClassIterator c, const unsigned int cidx) |
write next-split train/test intervals of class cidx (a single-split splitter never gets here, since its prepareNextSplit() returns false) | |
| virtual void | finishSplit () |
| post-loop state update shared by first/next split | |
| Protected Member Functions inherited from FST::Clonable | |
| void | set_cloned (const bool cloned=true) |
| marks/unmarks this instance as a clone; call from clone()/stateless_clone() overrides (Clonable_Impl does this automatically) | |
| void | set_sharing (const bool sharing=true) |
| marks/unmarks this instance as sharing (see is_sharing()) | |
| void | set_sharing_cloned (const bool cloned=true, const bool sharing=true) |
| sets both flags at once; call from sharing_clone() overrides (Clonable_Impl does this automatically) | |
Additional Inherited Members | |
| Protected Attributes inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| std::vector< PClassSplitter > | csplit |
| one TClassSplitter per data class, indexed by class index; grown on demand by assign()/set_n() | |
Detailed Description
template<class INTERVALCONTAINER, typename IDXTYPE>
class FST::Data_Splitter_Resub< INTERVALCONTAINER, IDXTYPE >
class FST::Data_Splitter_Resub< INTERVALCONTAINER, IDXTYPE >
Implements train/test data splitting: use all data both for training and then once more for testing.
Yields exactly one split, in which the train and test parts are the same samples. This is the one case where the contract's "train and test must not overlap" is deliberately broken, and the resulting accuracy is the RESUBSTITUTION estimate: how well a model reproduces the data it was fitted on.
- Warning
- A resubstitution estimate is optimistically biased, severely so for flexible models, and says nothing about generalization. It is legitimate as a training-fit diagnostic, as the upper reference point against which a held-out estimate is read, and for criteria that need no held-out part at all (the statistical filter criteria, which are computed on the training part). It is not a substitute for an honest estimate of classification accuracy.
Member Function Documentation
◆ getNoOfSplits()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverridevirtual |
number of splits this splitter yields (requires class sizes to have been set via set_n())
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ prepareNextSplit()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
advance split-sequence state; false = no more splits
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ print()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverridevirtual |
writes a human-readable identification of the splitter and its configuration; base default writes nothing
Reimplemented from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ splitClassFirst()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
write first-split train/test intervals of class cidx (c is that class's entry in csplit)
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ splitter_name()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
class name, used in error messages
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
The documentation for this class was generated from the following file:
- /Users/psms/dev/devtest1/_src_dataio/data_splitter_resub.hpp
Generated by
 1.17.0