Loading...
Searching...
No Matches
Public Types |
Public Member Functions |
Protected Types |
Protected Member Functions |
Private Attributes |
List of all members
FST::Data_Splitter_Leave1Out< INTERVALCONTAINER, IDXTYPE > Class Template Reference
Implements train/test data splitting: by means of leave-one-out. More...
#include <data_splitter_leave1out.hpp>
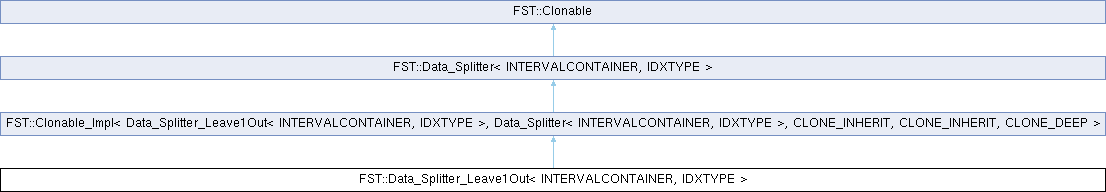
Inheritance diagram for FST::Data_Splitter_Leave1Out< INTERVALCONTAINER, IDXTYPE >:
Public Types | |
| typedef Clonable_Impl< Data_Splitter_Leave1Out, Data_Splitter< INTERVALCONTAINER, IDXTYPE >, CLONE_INHERIT, CLONE_INHERIT, CLONE_DEEP > | parent_impl |
| implements stateless_clone(); clone/sharing_clone throw in Data_Splitter | |
| Public Types inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| typedef std::shared_ptr< INTERVALCONTAINER > | PIntervaller |
| shared pointer to one class's list of train/test data intervals | |
Public Member Functions | |
| Data_Splitter_Leave1Out (const Data_Splitter_Leave1Out &dsp) | |
| virtual IDXTYPE | getNoOfSplits () const override |
| virtual std::ostream & | print (std::ostream &os) const override |
| writes a human-readable identification of the splitter and its configuration; base default writes nothing | |
| Public Member Functions inherited from FST::Clonable_Impl< Data_Splitter_Leave1Out< INTERVALCONTAINER, IDXTYPE >, Data_Splitter< INTERVALCONTAINER, IDXTYPE >, CLONE_INHERIT, CLONE_INHERIT, CLONE_DEEP > | |
| Data_Splitter< INTERVALCONTAINER, IDXTYPE > * | clone () const override |
| dispatches to the DEEP_KIND mechanism (default CLONE_DEEP: Derived's copy-constructor) | |
| Data_Splitter< INTERVALCONTAINER, IDXTYPE > * | sharing_clone () const override |
| dispatches to the SHARING_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Data_Splitter< INTERVALCONTAINER, IDXTYPE > * | stateless_clone () const override |
| dispatches to the STATELESS_KIND mechanism (default CLONE_INHERIT: defers to Base, which throws by family convention) | |
| Public Member Functions inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| Data_Splitter (const Data_Splitter &dsp) | |
Deep-copies every class's TClassSplitter (own train/test interval lists, not shared with dsp). | |
| void | assign (const unsigned int _clsidx, const PIntervaller _train, const PIntervaller _test) |
Registers class _clsidx's train/test interval lists (growing csplit as needed); the caller retains ownership via the shared pointers. | |
| void | set_n (const unsigned int _clsidx, const IDXTYPE _n) |
Sets class _clsidx's pattern count, which getNoOfSplits() and the concrete prepare*/splitClass* hooks size their splits against (growing csplit as needed). | |
| IDXTYPE | get_n (const unsigned int _clsidx) const |
the pattern count previously set for class _clsidx via set_n() | |
| bool | makeFirstSplit () |
| Produces the first split: prepareFirstSplit(), then splitClassFirst() per class, then finishSplit(). | |
| bool | makeNextSplit () |
| Produces the next split: prepareNextSplit(), then splitClassNext() per class, then finishSplit(). | |
| Data_Splitter * | clone () const override |
| Data_Splitter * | sharing_clone () const override |
| Public Member Functions inherited from FST::Clonable | |
| bool | is_clone () const |
| bool | is_sharing () const |
| true if this instance is a sharing_clone() result (referencing, not owning, the source's structures) | |
| bool | is_sharing_clone () const |
| true if this instance is BOTH a clone and sharing – i.e. specifically a sharing_clone() result, not a clone()/stateless_clone() one | |
Protected Types | |
| typedef Data_Splitter< INTERVALCONTAINER, IDXTYPE > | TCC |
| alias for the Data_Splitter base, used by the per-class hooks | |
| Protected Types inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| typedef std::shared_ptr< TClassSplitter > | PClassSplitter |
| shared pointer to one class's TClassSplitter | |
| typedef std::vector< PClassSplitter >::const_iterator | ClassIterator |
| iterator over csplit, as passed to the per-class splitClassFirst()/splitClassNext() hooks | |
Protected Member Functions | |
| virtual const char * | splitter_name () const override |
| class name, used in error messages | |
| virtual bool | prepareFirstSplit () override |
| set up split-sequence state; false = no split can be made | |
| virtual bool | prepareNextSplit () override |
| advance split-sequence state; false = no more splits | |
| virtual void | splitClassFirst (typename TCC::ClassIterator c, const unsigned int) override |
write first-split train/test intervals of class cidx (c is that class's entry in csplit) | |
| virtual void | splitClassNext (typename TCC::ClassIterator c, const unsigned int) override |
write next-split train/test intervals of class cidx (a single-split splitter never gets here, since its prepareNextSplit() returns false) | |
| virtual void | finishSplit () override |
| post-loop state update shared by first/next split | |
| Protected Member Functions inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| void | assert_csplit () const |
| DEBUG-only: asserts csplit is non-empty and every class has n>0 and non-null train/test lists. | |
| Protected Member Functions inherited from FST::Clonable | |
| void | set_cloned (const bool cloned=true) |
| marks/unmarks this instance as a clone; call from clone()/stateless_clone() overrides (Clonable_Impl does this automatically) | |
| void | set_sharing (const bool sharing=true) |
| marks/unmarks this instance as sharing (see is_sharing()) | |
| void | set_sharing_cloned (const bool cloned=true, const bool sharing=true) |
| sets both flags at once; call from sharing_clone() overrides (Clonable_Impl does this automatically) | |
Private Attributes | |
| IDXTYPE | pivot |
| which sample (index within pivotclass) to hold out as the current test pattern | |
| TCC::ClassIterator | pivotclass |
| which class the currently held-out sample belongs to | |
Additional Inherited Members | |
| Protected Attributes inherited from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE > | |
| std::vector< PClassSplitter > | csplit |
| one TClassSplitter per data class, indexed by class index; grown on demand by assign()/set_n() | |
Detailed Description
template<class INTERVALCONTAINER, typename IDXTYPE>
class FST::Data_Splitter_Leave1Out< INTERVALCONTAINER, IDXTYPE >
class FST::Data_Splitter_Leave1Out< INTERVALCONTAINER, IDXTYPE >
Implements train/test data splitting: by means of leave-one-out.
Yields one split per sample of the WHOLE data set, not per class: the splits walk class 0's samples one by one, then class 1's, and so on. In each split exactly one sample is the test part and everything else – including all of every other class – is the train part. The non-pivot classes therefore get an empty test part in that split, which is what a per-class accuracy accumulation has to expect.
The total number of splits equals the total number of samples, so leave-one-out is the most expensive validation protocol available: each of them retrains the model. Classes with no samples are skipped.
Constructor & Destructor Documentation
◆ Data_Splitter_Leave1Out()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inline |
pivotclass deliberately NOT copied: it is an iterator into the SOURCE's csplit list, which would be invalid here — split-loop state does not transfer, and prepareFirstSplit() must be called on the copy to (re)initialize it
Member Function Documentation
◆ finishSplit()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
post-loop state update shared by first/next split
Reimplemented from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ getNoOfSplits()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
overridevirtual |
number of splits this splitter yields (requires class sizes to have been set via set_n())
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ prepareFirstSplit()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
set up split-sequence state; false = no split can be made
Reimplemented from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ prepareNextSplit()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
advance split-sequence state; false = no more splits
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ print()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverridevirtual |
writes a human-readable identification of the splitter and its configuration; base default writes nothing
Reimplemented from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ splitClassFirst()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
write first-split train/test intervals of class cidx (c is that class's entry in csplit)
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ splitClassNext()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
write next-split train/test intervals of class cidx (a single-split splitter never gets here, since its prepareNextSplit() returns false)
Reimplemented from FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
◆ splitter_name()
template<class INTERVALCONTAINER, typename IDXTYPE>
|
inlineoverrideprotectedvirtual |
class name, used in error messages
Implements FST::Data_Splitter< INTERVALCONTAINER, IDXTYPE >.
The documentation for this class was generated from the following file:
- /Users/psms/dev/devtest1/_src_dataio/data_splitter_leave1out.hpp
Generated by
 1.17.0